Découvrir Pandipedia
Un répertoire grandissant de réponses utiles sélectionnées par la communauté Pandi. Cherchez dans la collection ou parcourez les dernières découvertes.
2292 entrées disponibles
Designing social media algorithms for civic resilience instead of engagement. Explores algorithmic objectives that prioritize informational quality and social cohesion. Reviews academic proposals and prototypes, and outlines implementation hurdles.
Executive summary
The literature contains a small but clear set of academic proposals that move social media ranking away from pure engagement and toward civic or social outcomes, including democratic discourse, offline civic participation, collective well-being, content quality, and social cohesion[1][2][3][4].
Evidence is uneven: the strongest items are conceptual proposals, while the most concrete tests are audits, field experiments, and a participatory prototype. Across those tests, changes in ranking or exposure can alter divisive content consumption and even affective polarization, but the work also shows important trade-offs and unresolved deployment questions[5][6][7].
Academic proposals for civic-resilience-oriented ranking
Several papers sketch alternative objectives for recommender systems. One proposes "alternative content recommendation algorithms" grounded in healthy civic discourse, the EU Digital Services Act, and democratic values, while explicitly discussing the trade-off between intervention and freedom of expression[8]. Another gives a framework for algorithms that may promote offline civic participation through attitudes, motivation, and social capital[9].
- A Collective Well-Being aware Recommender System (CWB-RS) is proposed inside an educational social media companion, with the goal of balancing external platform recommendations against a community-level well-being objective rather than engagement[10][11].
- The CWB-RS proposal says the system should help users access a more diverse set of perspectives and sources, provide opposite but not confrontational perspectives, reduce racist content by substituting low-harm feeds, and steer learners toward authoritative resources rather than extreme individual opinions[12][13][14].
- A separate normative paper proposes a "right to constructive optimization" for recommender systems under the Digital Services Act, framing the objective in terms of self-determination, self-development, inclusivity, political equality, reasonableness, and publicity[15].
- Adjacent quality and veracity ideas also appear in the sources: a Doximity audit emphasizes assessing content quality, and a fake-news review argues that crowdsourced veracity ratings can improve social media ranking algorithms[16][17].
- These proposals are mostly conceptual rather than deployed systems or completed field tests[18][19].
Prototypes and empirical tests
The clearest tested evidence in the supplied sources comes from ranking audits and live experiments, not from fully deployed civic-optimization platforms. These studies matter because they show that changing ranking rules can measurably change what users see and how they respond politically[20][21].
- A preregistered field experiment on X reranked feeds in real time with an LLM to increase or decrease exposure to antidemocratic attitudes and partisan animosity, and found that changing exposure shifted out-party partisan animosity by more than 2 points on a 100-point feeling thermometer[22].
- A Twitter audit compared the engagement-based timeline with a reverse-chronological baseline and a stated-preference timeline built from users' survey responses. It found that engagement-based ranking amplified more partisan, emotionally negative, and out-group hostile content, while the stated-preference ranking reduced negativity and divisiveness but could increase exposure to in-group content[23].
- A middle-school participatory design workshop produced the Social Sketch prototype, which experimented with removing likes and comments, using view counts instead, adding tags and filters, and exploring anonymity and personalization as ways to support social wellbeing[24].
- For informational quality, the Doximity paper and the fake-news review are best read as adjacent evidence that quality and veracity can be treated as ranking objectives, but they are not direct field tests of civic-resilience ranking[25][26].
Implementation hurdles and evaluation gaps
The main hurdle is defining a valid objective function. Across the sources, the candidate targets differ: civic participation, democratic discourse, collective well-being, quality, veracity, social cohesion, and social confidence. The literature does not yet show a single validated metric that can reliably unify those goals for deployment[27][28][29][30].
A second hurdle is trade-off management. The Twitter audit warns that optimizing stated preferences could increase in-group bias, the societal-good paper highlights tension with freedom of expression, and the audit paper says more research is needed before real-world deployment because of technical and platform-incentive challenges[31][32].
A third hurdle is evaluation. The strongest evidence today comes from narrow experiments, audits, and prototypes, which means the field still lacks broad proof that civic-optimized ranking improves downstream civic resilience at scale[33][34][35].
Compact evidence table
| Item | Study type | Main contribution | Limitation or status |
|---|---|---|---|
| Designing social media content recommendation algorithms for societal good[36] | Perspective / PubMed record[37] | Proposes alternative recommendation algorithms rooted in civic discourse, democratic values, and the EU Digital Services Act[38] | Conceptual proposal, not a deployed system[39] |
| How Social Media Algorithms Shape Offline Civic Participation[40] | Theoretical framework / review article[41] | Frames how algorithms may influence offline civic participation through attitudes, motivation, and social capital[42] | Framework paper rather than an implementation test[43] |
| Challenging social media threats using collective well-being-aware recommendation algorithms and an educational virtual companion[44] | Proposal paper[45] | Introduces a CWB-RS and virtual companion that balance platform recommendations around collective well-being[46] | Conceptual and educational, not a completed field deployment[47] |
| A Right to Constructive Optimization[48] | Normative legal and policy paper[49] | Defines a public-interest benchmark for recommender systems under the Digital Services Act[50] | Normative framework, not an empirical test[51] |
| Engagement, user satisfaction, and the amplification of divisive content on social media[52] | Preregistered audit / counterfactual ranking comparison[53] | Compares engagement, reverse-chronological, and stated-preference feeds and shows different divisiveness effects[54] | Authors note concerns about in-group bias, technical deployment, and platform incentives[55] |
| Reranking partisan animosity in algorithmic social media feeds alters affective polarization[56] | Field experiment[57] | Shows that live feed reranking can shift partisan animosity[58] | Strong causal evidence, but limited to a specific platform and outcome window[59] |
| Prototyping for Social Wellbeing with Early Social Media Users[60] | Participatory design prototype[61] | Tests design changes such as removing likes and comments, using view counts, and adding filters or anonymity[62] | Prototype stage, not a population-scale ranking system[63] |
Conclusion
Overall, the supplied literature suggests that civic-resilience ranking is best understood as a portfolio of alternative objectives, not a single replacement for engagement. The field already has credible conceptual proposals and a few meaningful tests, but it still needs validated civic metrics, clearer treatment of free-expression and bias trade-offs, and more evidence on whether these designs work beyond audits and prototypes[64][65][66][67].
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Urban tree canopies: cooling, value, biodiversity, and targets
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Can Quantum Computing Help Save Coral Reefs?
Transcription
Yes, but not yet. Quantum computing could help coral reefs mainly by improving the models and decisions that guide conservation. Researchers have already linked it to marine biodiversity work, including population genetics, species distribution modelling, genomic analysis, ecosystem simulation, and ocean monitoring. In environmental science, the most promising uses are solving differential equations and fluid dynamics faster, improving machine learning for hard to model processes, and helping tune and optimize complex simulations. That matters for reefs because reef models often struggle with scale, cost, uncertainty, and mixed quality data. Better computation could support more detailed larval dispersal and connectivity studies, more careful planning for marine protected areas, and better testing of conservation options. But the evidence is still mostly indirect. The reef sources show the modelling problems clearly, while the quantum sources point to general environmental and marine applications rather than proven reef breakthroughs. So the realistic answer is hopeful, not proven: quantum computing may eventually strengthen reef conservation, but direct reef specific evidence is still limited.
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Protein structure datasets for ML training and benchmarking



Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Kraftwerk: man-machine minimalism
There is no difference between a musician and a technicianRalf Hütter[1]
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
What is the process of genetic engineering?
Transcription
The process of genetic engineering involves the direct manipulation of an organism's DNA to alter its characteristics. This typically includes several steps: isolating a specific gene, modifying it if necessary, inserting it into a suitable vector such as plasmids, and then introducing this construct into the target organism via various transformation techniques. The modified organism, often referred to as genetically modified (GM), can exhibit new traits or produce desired proteins, such as in the case of bacteria engineered to produce insulin or crops enhanced for better yield and resistance to diseases [1][4][8].
Sources
- Genetic engineering | Definition, Process, Uses, Examples, Techniques, & Facts
- The process of genetic engineering - Higher - Changing the genes - Edexcel - GCSE Combined Science Revision - Edexcel
- What is genetic engineering?
- Genetic engineering - Genetic engineering - National 5 Biology Revision
- Genetic Engineering
- Genetic engineering - DNA Modification, Cloning, Gene Splicing
- Genetic Engineering - The Definitive Guide
- 1.12: Genetic Engineering
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
What are effective daily habits?
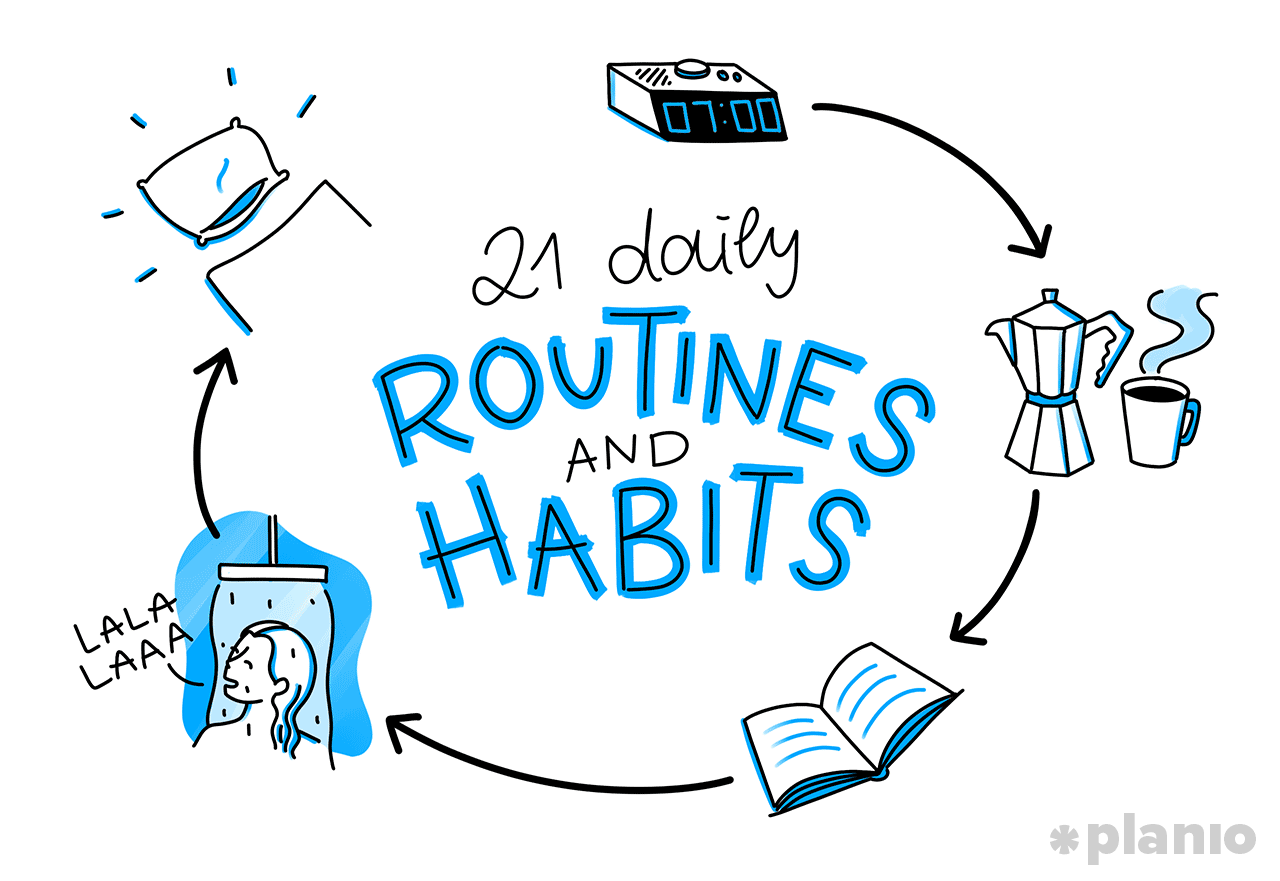
Effective daily habits can significantly enhance productivity and wellbeing. Starting your day with a consistent morning routine, such as waking up early and incorporating physical activity, sets a positive tone. Engaging in practices like positive affirmations and mindfulness can further influence mood and decision-making throughout the day[1][2].
During work hours, respecting your energy cycles and taking regular breaks promotes better focus and reduces burnout[2][3]. Additionally, maintaining good hydration and practicing gratitude can contribute positively to mental and physical health[3][6]. Implementing these habits gradually will lead to lasting improvements in your daily life[4][5].
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
What legacy did Malala Yousafzai leave for education rights?
Transcription
Malala Yousafzai's legacy for education rights includes her relentless fight against the Taliban's prohibition of girls' education and her establishment of the Malala Fund, which advocates for girls' access to education globally. She became the youngest Nobel laureate at 17, highlighting her impact on children’s rights through her activism. Her memoir and speeches emphasize education as a fundamental right, inspiring millions around the world to advocate for educational equity and women's empowerment [1][2][3][5][9].
Sources
- Biography: Malala Yousafzai
- The Legacy of Malala Yousafzai: Education, Awards, and Activism
- Malala Yousafzai | Biography, Nobel Prize, & Facts
- Malala's Story | Malala Fund | Malala Fund
- Nobel Laureate Malala Yousafzai Calls for Full Cease-Fire in the Israel-Hamas War
- Malala explains why she risked death to speak up for girls’ education
- Malala Yousafzai: Why I Fight for Education
- Malala: How A Young Girl Became A World Symbol
- Student Learning Resources: The Fight for Human Rights
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Navigating data privacy laws in the age of generative AI: GDPR, CCPA, and beyond. Compares major regulations, outlines compliance checklists, and reviews upcoming legislative proposals. Helps global firms avoid costly penalties.
Generative AI Privacy Compliance: GDPR, CCPA/CPRA, UK Guidance, and the EU AI Act
This dossier compares the main privacy obligations that matter for generative AI across the official EU, California, and UK materials in the research corpus, then turns them into a practical global compliance checklist. The strongest evidence in the corpus is from GDPR, California CCPA/CPRA materials, UK ICO guidance, and the EU AI Act, so I am keeping the broader "other major regimes" point cautious and scoped to what was actually extractable.
At a high level, the shared compliance pattern is consistent: identify a lawful basis or disclosure rule, minimize and document data use, protect individual rights, secure the system, and keep governance evidence ready for regulator review. For AI model development specifically, the EDPB says legitimate interest can be used only after a necessity and balancing analysis, and that unlawfully processed training data can affect deployment unless the model has been duly anonymised.[1]
Current Compliance Requirements by Regime
| Regime | Core compliance requirements for generative AI | AI-specific implication |
|---|---|---|
| GDPR + EDPB | GDPR requires a lawful basis, transparent information, purpose limitation, data minimisation, DPIAs for high-risk processing, and safeguards for profiling, automated decision-making, and transfers.[2][3] | The EDPB's 2024 AI-model opinion treats AI development and deployment as a GDPR analysis problem, not as an exception to it, and stresses necessity, balancing, transparency, and the effect of unlawful data use on deployment.[4] |
| California CCPA/CPRA | California requires notice at collection, consumer rights to know and delete, opt-out of sale or sharing, non-discrimination, contract controls for service providers and contractors, and reasonable security procedures and practices.[5][6] | The statute also defines profiling and authorizes regulations for cybersecurity audits where processing presents significant privacy or security risk, which is especially relevant for AI systems that use large-scale personal data.[7] |
| UK GDPR / ICO guidance | The ICO guidance centers AI compliance on accountability and governance, transparency, lawfulness, accuracy, fairness, bias and discrimination, Article 22, security, minimisation, and individual rights handling.[8] | This is regulator guidance rather than a new statute, so firms should use it as the UK supervisory authority's playbook for evidence of good practice in AI deployment.[9] |
| EU AI Act overlay | The EU AI Act adds transparency, technical documentation, and record-keeping obligations for AI systems, while reaffirming that data minimisation and data protection by design and by default still apply across the AI lifecycle.[10] | For generative AI, the practical effect is an added governance layer on top of privacy law, especially where the system is high-risk or interacts with biometric, profiling, or other sensitive use cases.[11] |
Practical Checklist for Global Firms
- Map every gen-AI use case, identify whether personal data is ingested, generated, fine-tuned, logged, or shared, and assign controller, processor, service-provider, or contractor roles before launch.[12][13][14][15][16]
- Document the lawful basis or statutory disclosure rule, then provide a clear privacy notice or notice at collection that matches actual data flows and secondary uses.[17][18][19]
- Minimize training and inference inputs, limit retention, and avoid reusing data for new purposes unless the new purpose is separately justified and disclosed.[20][21][22]
- Build rights-handling workflows for access, deletion, correction, objection, opt-out, and, where relevant, automated-decision safeguards and human review paths.[23][24][25][26]
- Run DPIAs or equivalent risk assessments for high-risk AI, profiling, or automated-decision uses, and record mitigations, residual risk, and approval sign-off.[27][28][29][30]
- Use written contracts that restrict vendor or downstream use, require deletion or return where appropriate, and align with processor, service-provider, and contractor limits.[31][32][33]
- Apply security controls that are appropriate to the sensitivity and scale of the data, including access control, logging, incident response, and remediation procedures.[34][35][36][37]
- Keep governance records that show purpose limitation, data minimisation, testing, monitoring, and escalation decisions, because transparency and documentation are recurring enforcement touchpoints across the corpus.[38][39][40]
Upcoming Changes Affecting Compliance and Penalty Risk
The clearest near-term overlay in the corpus is the EU AI Act, because it introduces AI-specific documentation, transparency, and record-keeping duties that sit on top of existing privacy compliance and can increase exposure if firms cannot prove lifecycle controls.[41] California is also moving in a tighter-risk direction, because the statutory text contemplates cybersecurity-audit regulations for processing that presents significant privacy or security risk, which can raise both compliance cost and enforcement exposure for AI-heavy businesses.[42] The EDPB's 2024 AI-model opinion shows that regulators are actively testing how GDPR principles apply to AI training and deployment, so lawful-basis, transparency, and unlawful-data questions are likely to remain enforcement flashpoints.[43]
I am not extending the report to a separate UK bill forecast because the parliamentary source in the research run was blocked, so the UK discussion here is limited to current ICO guidance and UK GDPR practice. Likewise, I am not making substantive conclusions about Brazil, Quebec, or Singapore because the separate official-source extraction for those jurisdictions did not succeed.
Evidence and Scope Limitations
| Source type | Source | What it supports | Scope note |
|---|---|---|---|
| Primary EU law | GDPR[44] | Baseline privacy principles for AI data use, rights, DPIAs, and transfers.[45] | Strongest source for general privacy architecture in the corpus. |
| Primary EU regulator guidance | EDPB AI-model opinion[46] | How GDPR principles apply to model development and deployment, especially legitimate interest and unlawful training data.[47] | Interpretive, not a statute, but highly persuasive for EU enforcement posture. |
| Official California guidance | CCPA OAG page[48] | Notice, consumer rights, opt-out, and security framing for businesses.[49] | Consumer-facing explanation of the California privacy framework. |
| Primary California statute | California Civil Code text[50] | Contract limits, security duty, profiling definition, and audit-rulemaking authority.[51] | Useful for operational controls and penalty-risk planning. |
| Official UK regulator guidance | ICO AI guidance[52] | Accountability, transparency, fairness, security, minimisation, and rights handling for AI systems.[53] | Guidance, so use it as a governance benchmark rather than a new legal code. |
| Primary EU AI law | EU AI Act[54] | Transparency, documentation, record-keeping, and lifecycle controls that overlay privacy compliance.[55] | Important because it compounds privacy obligations for many AI deployments. |
| Scoped limitation | Brazil LGPD, Quebec private-sector law, Singapore PDPA | Not included in the conclusions because the separate official extraction failed. | Do not read the report as a comprehensive global survey beyond the sources above. |
Conclusion
For generative AI, the practical compliance answer is not a single new privacy rule, but a layered program built from GDPR-style principles, California consumer-rights and contract controls, UK accountability guidance, and the EU AI Act's additional documentation and transparency layer.[56][57][58][59][60] Firms that can show lawful basis or notice, minimization, rights handling, risk assessment, security, and vendor governance are best positioned to reduce both compliance friction and penalty risk.[61][62][63][64][65]
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
World Records Built on Glitches
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).