Découvrir Pandipedia
Un répertoire grandissant de réponses utiles sélectionnées par la communauté Pandi. Cherchez dans la collection ou parcourez les dernières découvertes.
1669 entrées disponibles
Could Quantum Loot Drops Make Gaming Fairer?
Transcription
Imagine opening a loot box and knowing the outcome was generated by nature itself. Quantum random number generators use the unpredictability of quantum physics to produce what researchers call true randomness, and some systems add self-certification intended to make that randomness verifiable. For loot drops, that could strengthen trust. Players and publishers might be able to audit whether a draw was genuinely unpredictable. But quantum randomness does not make the reward system fair by itself. A draw can be truly random while the odds remain stingy, the rarest items remain extremely unlikely, or the wider game economy and monetisation still favour the seller. Fair randomness and fair design are different questions. There is also an excitement trade-off. Research finds that rarer loot-box rewards produce stronger arousal, feel more rewarding, and increase the urge to open another box. Loot-box purchasing has also been associated with problem gambling, although the evidence is correlational and does not prove that buying loot boxes causes it. And quantum technology is not a magic upgrade. The supplied evidence does not establish its latency, infrastructure demands, certification standards, or superiority over ordinary pseudorandom systems, which are not compared here. So the real revolution may be accountability, not simply unpredictability: transparent odds, responsible monetisation, and verifiable draws. If a quantum roll is perfectly random but the game is not fair, has anything important changed?
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Which quantum programming language was originally developed by Google for its processors?. Answer: Cirq.
Cirq was originally developed by Google for programming and running quantum circuits on its processors.
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
Créez votre compte pour façonner ce Feed autour de ce que vous cherchez et aimez.
Post-Quantum Cryptography Migration: An Enterprise Playbook
Post-Quantum Cryptography Migration: An Enterprise Playbook
A post-quantum cryptography (PQC) programme should be treated as a risk-managed transformation, not a one-time algorithm swap. The practical sequence is: establish governance, build a living cryptographic inventory, prioritise long-lived and high-impact dependencies, select standards-based algorithms, validate them in controlled pilots, document decisions and residual risk, coordinate suppliers, and then execute a phased rollout with measured fallback and retirement controls.[1][2][3]
This playbook distinguishes documented guidance from proposed enterprise operating controls. The supplied research supports ML-KEM for key establishment, ML-DSA for general-purpose signatures, selective use of SLH-DSA, and hybrid traditional plus PQC transition patterns. It does not support treating HQC as a current production replacement for ML-KEM or treating illustrative performance gates as universal requirements.
1. Mobilise the Programme and Set Governance
Create a named quantum-readiness team before technical discovery. Include IT and OT procurement specialists, cybersecurity risk managers, privacy risk managers, security architecture, engineering, operations, legal, compliance, business owners, and supplier-management representatives. Assign an executive sponsor with authority over funding, ownership disputes, and risk acceptance; the cited guidance supports executive sponsorship and formal risk governance but does not prescribe a particular job title.[4][5]
- Approve a programme charter covering scope, decision rights, reporting cadence, data-quality rules, exceptions, escalation, and funding. These operating details are proposed implementation controls derived from the guidance’s emphasis on formal governance and measurable progress.[6]
- Make the inventory a controlled, continuously updated enterprise record rather than a one-time spreadsheet. NIST describes a centralised inventory of cryptographic data and metadata, with analytics and policy-driven findings supporting migration decisions.[7]
- Give each record an accountable business or technical owner, operational contact, and risk owner. This is a recommended control based on the guidance’s focus on clear operational and risk roles, not an explicitly prescribed NIST field.[8][9]
- Approve a phased roadmap with milestones, target dates, investment, capability requirements, dependencies, and escalation paths. The NCSC migration-timelines guidance recommends phased planning and prioritisation of systems with high impact or long migration lead times.[10]
2. Build the Cryptographic Asset Inventory
Start with quantum-vulnerable public-key signatures and key-establishment mechanisms. The NIST discovery project places symmetric ciphers and hash functions outside its immediate scope because they are less drastically affected by a cryptographically relevant quantum computer, although the wider inventory should still record cryptographic context where it affects dependencies.[11]
Use both top-down architectural analysis and bottom-up technical discovery. Begin with core services and dependencies, then inspect managed IT and OT cryptography, protocols, hardware, certificates, libraries, binaries, running processes, and certificate stores. Include cloud and managed services, products, suppliers, software-development pipelines, HSMs, firmware, and network infrastructure.[12][13][14]
- Asset and deployment: system, service, application, product, hardware, firmware, HSM or cryptographic module, cloud or managed-service environment, version, and patch level.[15][16]
- Cryptographic implementation: algorithm, protocol, library, embedded code, certificate, key, keystore, PKI component, enabled service, and application or module managing the key.[17]
- Security function: signature, identity authentication, key transport or establishment, key management, software update, firmware validation, or another public-key use.[18][19]
- Protection target: data or business function protected, data state, sensitivity, adversary value, required confidentiality lifetime, and collect-now-decrypt-later exposure.[20][21][22]
- Dependencies and ownership: upstream and downstream services, clients, protocols, suppliers, cloud providers, processors, accountable owner, operational contact, and risk owner.[23][24]
- Risk and status: quantum-vulnerable object, criticality, exposure, compliance driver, certificate lifecycle state, migration state, exception, remediation date, and residual risk.[25]
3. Prioritise and Select the Target Cryptography
Rank assets by business impact, confidentiality lifetime, collect-now-decrypt-later exposure, migration lead time, hardware or firmware constraints, supplier dependency, protocol complexity, and replacement difficulty. Prioritisation should expose the systems that are both consequential and slow to change, rather than simply counting vulnerable cryptographic objects.[26][27][28]
Use the following decision baseline, subject to protocol profiles, implementation support, cryptographic-module validation, interoperability, and applicable regulatory requirements.
| Option | Enterprise role | Decision and caveat |
|---|---|---|
| ML-KEM, FIPS 203 | Primary PQC key-establishment option | Use for new or upgradeable systems that establish encryption keys. Benchmark message size, bandwidth, latency, acceleration, and interoperability. |
| ML-DSA, FIPS 204 | General-purpose PQC signatures | Evaluate for software, certificates, documents, device identities, and similar signing uses. Larger keys and signatures can affect storage, network transactions, certificate handling, throughput, and verification latency. |
| SLH-DSA, FIPS 205 | Alternative hash-based signature family | Use selectively where algorithm diversity, conservative hash-based assumptions, or an assurance decision justifies it. Validate size, performance, and ecosystem support rather than treating it as an automatic ML-DSA replacement. |
| Hybrid traditional plus PQC | Transition interoperability pattern | Use where endpoints, vendors, protocols, or certificate ecosystems are not ready for pure PQC. Confirm the exact composition, authentication, negotiation, and recording behaviour; RFC 9794 terminology does not mandate one universal enterprise profile.[29] |
| HQC | Future key-establishment diversity option | Track for future standards, validated implementations, protocol integration, and vendor roadmaps. It is not the current replacement for the ML-KEM deployment baseline. |
4. Run Bounded Pilots Before Production
NIST NCCoE migration work treats discovery, interoperability testing, and benchmarking as laboratory activities intended to expose integration problems before production; the relevant materials are preliminary guidance rather than a complete production cutover method.[30][31][32]
- Create a representative, non-production lab containing relevant browsers, clients, servers, proxies, load balancers, HSMs, service-mesh components, middleboxes, DevOps tooling, virtual and hardware endpoints, and captured traffic where appropriate.[33][34]
- Select two or three bounded services, such as an internal HTTPS API, a browser-facing service, and an administrative SSH path. Record the classical baseline, software versions, configuration hashes, payload sizes, connection rate, and failure rate. These bounded-service choices and recording requirements are proposed operational practice.
- Test positive negotiation for supported hybrid and pure-PQC groups, legacy-peer behaviour, unsupported groups, malformed shares, HelloRetryRequest, timeouts, rejected shares, classical-only negotiation, and downgrade-related cases.[35][36]
- Measure ClientHello and total handshake size through firewalls, proxies, and middleboxes. IETF application guidance warns that duplicating PQC KEM public-key shares can create packet-size problems.[37]
- Instrument algorithm and peer negotiated, retries, failures, timeouts, rejection reasons, certificate errors, resource saturation, and application errors. Ensure that fallback activation is visible rather than silently misclassified; the monitoring fields and alert thresholds are proposed enterprise controls grounded in the interoperability guidance.[38]
- Rehearse rollback to the last known-good configuration and test fallback before limited production exposure. A rollback runbook should identify the change owner, configuration artifact, approval path, data-preservation steps, health checks, and the condition that ends the rollback. These runbook details are proposed operational controls.
5. Benchmark and Set Service-Specific Gates
NIST identifies laboratory performance benchmarking as a way to optimise implementations toward production readiness and to inform use-case algorithm selection, but the supplied research does not provide validated universal numerical results for PQC latency, CPU, bandwidth, memory, or handshake impact.[39] Run the same workloads with the classical baseline, each candidate hybrid configuration, and any pure-PQC configuration under consideration, across normal and peak load, high concurrency, small and large payloads, cold and resumed sessions, and representative hardware.[40]
| Measure | Record | Illustrative proposed gate |
|---|---|---|
| Handshake latency | Median, p95, and p99 by protocol and algorithm | p95 increase no greater than 20% versus classical baseline. This is an illustrative enterprise threshold, not documented universal guidance.[41] |
| Handshake success | Successful, retried, timed-out, and rejected handshakes by peer, algorithm, and reason | At least 99.9% for supported pilot pairs, excluding deliberately negative tests. This is a proposed gate, not a standards requirement.[42] |
| Message size | Handshake bytes, fragmentation, retransmissions, and middlebox failures | No unexplained fragmentation or middlebox failure; set a service-specific ceiling from the baseline path.[43] |
| Resource cost | CPU, memory, connection rate, and network egress at peak | Retain the service’s existing operational reserve. This is a proposed capacity-control criterion. |
| Application effect | Request latency, throughput, error rate, and tail latency under PQC | Approve only if service-level objectives remain satisfied. The precise threshold must be set by the service owner. |
6. Document Compliance, Risk, and Approval Evidence
Maintain an evidence pack that allows an independent reviewer to reconstruct scope, prioritisation, decision rationale, approvals, testing, and residual-risk treatment. NCSC guidance supports discovery, prioritisation, roadmap development, executive sponsorship, supplier engagement, and sharing progress, but does not prescribe a complete evidence schema.[44]
- Programme charter and accountability record, including sponsor, owners, security, procurement, legal, compliance, and supplier-management contacts.[45]
- Prioritisation record for each service, including impact, data lifetime, lead time, dependencies, exposure, treatment decision, residual risk, and review date.[46]
- Versioned roadmap and investment case with milestones, targets, capability requirements, dependencies, acceptance criteria, and escalation paths.[47]
- Decision and exception register covering deferrals, unsupported platforms, compensating controls, supplier exceptions, and temporary fallbacks. Include owner, evidence reviewed, expiry trigger, renewal conditions, and retirement criteria. This is a proposed enterprise control, not a detailed mandatory requirement in the cited guidance.
- Pilot exit pack containing test plan, interoperability results, benchmark data, defects, rollback rehearsal, fallback disposition, and production approver.
- Production approval pack containing deployment record, monitoring plan, fallback activation criteria, change approval, and updated inventory. These evidence-pack structures are proposed controls tailored from the cited guidance.[48]
7. Coordinate Vendors and Procurement
Treat supplier readiness as part of enterprise readiness. CISA identifies cloud services, web software, networking hardware and software, and endpoint security as product categories relevant to PQC-capable investment; NCSC recommends incorporating PQC into supplier security assessments and sourcing.[49][50]
The following are proposed enterprise procurement and contract controls, not authoritative mandatory clauses. Legal, procurement, risk, and regulatory teams should tailor them to the service and jurisdiction.[51][52]
- Require suppliers to state whether each product supports PQC now, is upgradeable, or has no committed path, and to identify supported ML-KEM, ML-DSA, SLH-DSA, and hybrid profiles where applicable.[53]
- Request roadmaps, firmware, operating-system, library, HSM, managed-service, and end-of-support dependencies, with notification of material changes.
- Require evidence of crypto-agility, defined as the ability to replace or adapt cryptographic algorithms across relevant protocols, applications, hardware, firmware, and infrastructure while preserving secure operation. Exact acceptance tests remain an enterprise decision.[54]
- Coordinate end-to-end testing across supplier products, supported peers, certificate and key migration, configuration export, proxies, load balancers, and managed-service boundaries.
- Record supplier test results, unresolved interoperability defects, support dates, upgrade dependencies, lifecycle commitments, and named escalation contacts in the supplier-risk file.[55]
- For renewals and major upgrades, make PQC capability or upgradeability an evaluation criterion, and require a documented transition and support plan. This reflects NCSC and CISA recommendations, while the precise scoring and contractual remedy are proposed controls.[56][57]
8. Control Fallback, Rollout, and Retirement
Choose fallback per dependency rather than applying one enterprise-wide switch. The permitted treatment may be a hybrid configuration, a temporarily retained traditional mechanism, an alternate standardised PQC algorithm, or service isolation and replacement. A classical-only path must never be represented as quantum-safe.
- For every fallback, record the affected dependency, reason, owner, risk acceptance, allowed scope, monitoring signal, activation condition, expiry date or trigger, and retirement criteria. These controls implement the research recommendation that fallback be time-bounded and governed by explicit ownership and expiry.
- Roll out in waves from pilot services to higher-impact services, using canary exposure and an approved rollback point. The phased roadmap and prioritisation approach are supported by NCSC migration-timelines guidance.[58]
- Monitor negotiated algorithm, fallback frequency, handshake failures, latency, message-size failures, resource headroom, certificate errors, and application-level errors. Alert on unexpected classical-only negotiation, repeated fallback, expiry approach, or regression against the approved baseline. The monitoring design and thresholds are proposed operational controls informed by the pilot guidance.[59]
- Retire a fallback when the dependency supports the approved PQC or hybrid profile, interoperability and performance gates pass, monitoring is stable for the service’s defined observation period, and the service owner and risk authority approve removal. The observation period and approval thresholds are proposed enterprise criteria.
- If a supplier cannot meet the migration path, isolate or replace the dependency, retain only the documented time-bounded exception, and escalate before its expiry rather than renewing it silently.[60]
Conclusion: The Migration Control Loop
The durable operating model is a loop: discover, prioritise, select, test, document, coordinate, deploy, monitor, and retire exceptions. Begin with ML-KEM and ML-DSA as the current planning baseline, use SLH-DSA only for a defined diversity or assurance need, use hybrid profiles to manage interoperability, and track HQC as future diversification rather than a present default.
Success is not merely enabling a PQC option. It is proving that each critical dependency has an accountable owner, an evidence-backed migration decision, a tested protocol path, measured performance against a classical baseline, a visible rollback mechanism, and a time-bounded fallback that cannot become permanent by inaction.[61][62][63]
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
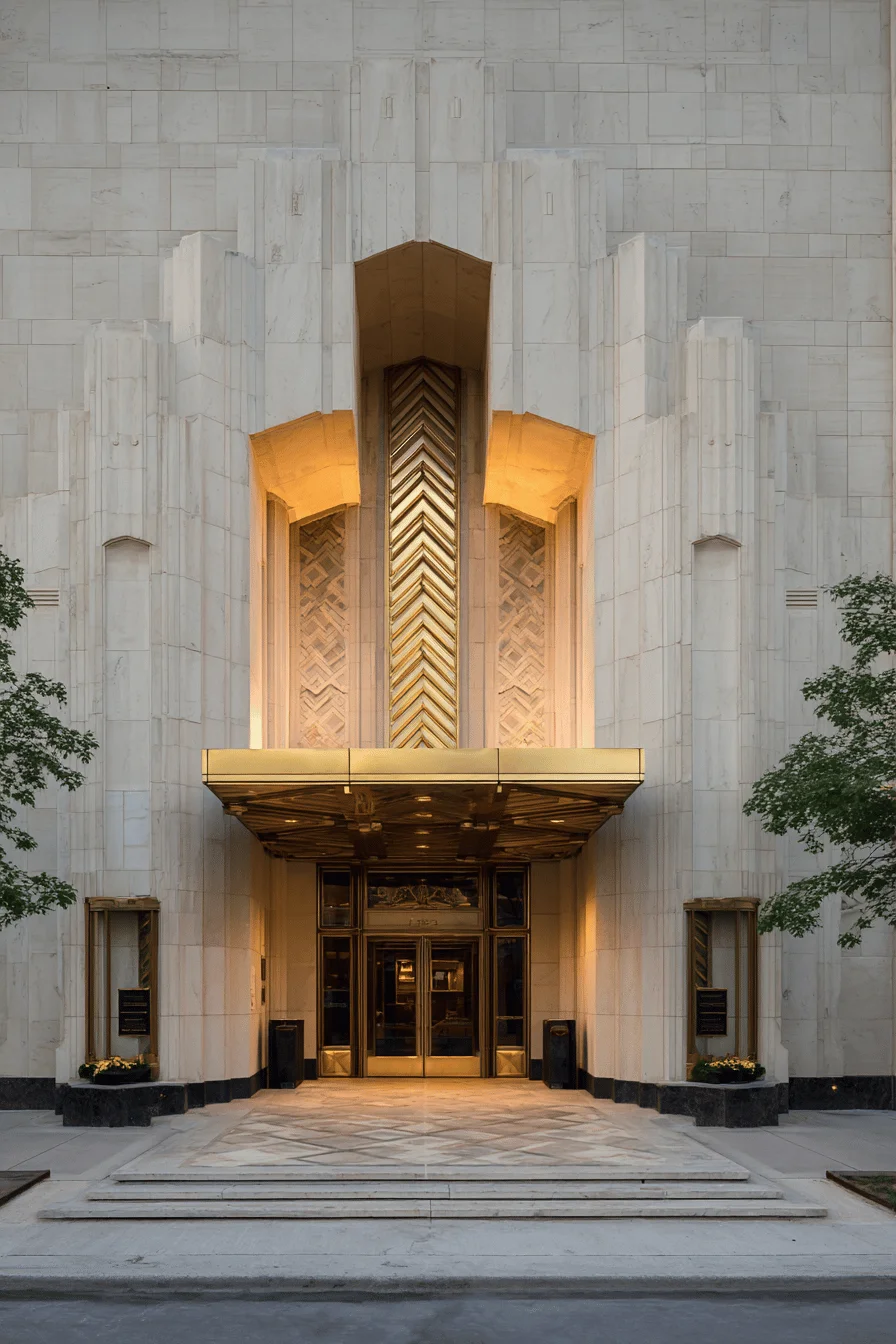
Art Deco in Motion


Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
The Frog That Hides Its Blood
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).


Créez votre compte pour façonner ce Feed autour de ce que vous cherchez et aimez.
How do quantum random number generators enhance cryptographic systems?
Quantum random number generators (QRNGs) enhance cryptographic systems by drawing entropy directly from quantum events that are unpredictable and cannot be replicated, rooting randomness in physics rather than software algorithms [1].
The Physics of True Randomness
Unlike classical random number generators, which rely on deterministic rules, thermodynamics, or pseudo-random algorithms that can be exploited by a sufficiently smart computer, quantum phenomena possess a built-in probabilistic nature [2][3]. Quantum random number generators exploit these quantum mechanics to generate truly random numbers [4]. For example, recent scientific demonstrations have used entangled qubits and random circuit sampling to roll quantum dice, forcing a quantum computer to generate numbers certified as truly random and physically beyond the prediction of even the most powerful supercomputers [5].
Security Advantages Over Pseudo-Random Generators
Pseudo-random number generators and traditional true random number generators rely on classical physics or software rules that leave room for underlying patterns [6][7]. In contrast, quantum randomness provides the highest level of cryptographic security because the underlying quantum events have no hidden variables or predictable patterns [8][9]. This ensures that encryptions remain impossible to break via predictive computation, supporting secure financial transactions, sensitive communications, and the prevention of unauthorized access [10][11].
Practical Deployment Notes
- Regulatory Compliance: Cryptographic products used in regulated environments must often comply with standards like FIPS 140, which incorporates frameworks such as NIST SP 800-90B to assess entropy source quality [12]. Certain software QRNG solutions have achieved NIST SP 800-90B Entropy Source validation, allowing them to integrate with NIST-approved solutions without requiring recertification [13].
- Hardware and Integration: Quantum randomness is deployed commercially in data centers, smart devices, hardware security modules, firewalls, public key infrastructures (PKIs), and Internet of Things (IoT) devices [14]. Certain software-based quantum entropy sources require no network connectivity, making them well-suited for air-gapped systems and critical infrastructure [15].
- Industry Adoption: Financial institutions and regulated industries are actively piloting and combining quantum randomness with post-quantum cryptography to future-proof digital assets against emerging threats like store-now-decrypt-later attacks [16].
Would you also like to know how NIST standards evaluate entropy sources for cryptographic systems?Réponse terminée. Une option de suivi est disponible.
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
GMO Bananas: Five Myths, Five Evidence-Based Facts
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
What are digital twins in healthcare?

Medical digital twins are dynamic, data-driven virtual representations of physical individuals or human body parts that evolve alongside their human counterparts [1][2]. These patient-specific virtual replicas—often called "patients-in-silico"—are continuously updated with streams of health data such as lab results, imaging, genetic profiles, and wearable device outputs [3]. By merging artificial intelligence with mechanistic disease modeling, medical digital twins can simulate biological processes, predict disease progression, and forecast treatment outcomes [4][5]. Key clinical applications include diagnosis support, surgery planning, and treatment prediction across fields like oncology and diabetes management [6].
Despite their potential, implementing medical digital twins faces significant hurdles. Regulatory and ethical challenges include navigating patient consent for continuously updating models, establishing data privacy and security, and determining clear governance and accountability frameworks if a prediction leads to an error [7]. Data integration hurdles involve acquiring accurate, real-time data, synchronizing multimodal information, and harmonizing health data typically stored in diverse formats and systems [8]. Furthermore, ensuring trust requires rigorous verification, validation, and uncertainty quantification to assess model accuracy and reliability [9].
Would you also like to know how medical digital twins combine AI with mechanistic modeling?Réponse terminée. Une option de suivi est disponible.
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).
How might quantum computing intersect with protein folding research?
Quantum computing intersects with protein folding research by tackling the extreme combinatorial complexity of predicting a protein's three-dimensional structure from its amino acid sequence [1]. Because the conformational space of a protein is vast, classical brute-force methods become infeasible [2]. Quantum computing offers a promising path forward by simulating nature directly and exploring countless conformations and energy states much faster than classical methods [3][4].
Theoretical Speedups for Energy Landscape Calculations
To model protein folding on quantum hardware, researchers often map coarse-grained protein models onto discrete lattices (such as tetrahedral or face-centered cubic lattices) using sparse encoding schemes where amino acid turns are represented by qubits [5][6].
The primary computational mechanism relies on hybrid quantum-classical algorithms like the Variational Quantum Eigensolver (VQE) and the Quantum Approximate Optimization Algorithm (QAOA) [7]. These algorithms optimize a parameterized quantum circuit to approximate the ground state of a Hamiltonian, which mathematically represents the system's energy landscape to reveal the most stable protein configuration [8]. By employing sampling-based optimization techniques—such as Conditional Value-at-Risk (CVaR) objectives combined with population-based or Monte Carlo optimizers—quantum approaches can navigate high-dimensional energy landscapes without relying on gradients, thereby avoiding barren plateau traps [9]. Advanced workload reduction strategies, observable grouping, and circuit packing further enhance these methods by dramatically lowering measurement overhead and cutting execution costs and runtimes [10].
Proof of Concept Demonstrations and Hardware Limits
Proof-of-concept experiments have successfully scaled to several small peptide sequences:
* 6 and 8 amino acid models: Early coarse-grained models were folded on 2D and 3D lattices using quantum annealers [11].
* 7-amino acid neuropeptide (APRLRFY): Implemented on a 9-qubit model using 90 physical qubits on an IBM quantum device via circuit packing [12].
* 9-amino acid Bradykinin (RPPGFSPFR): Evaluated via a 17-qubit model across classical simulators and IBM quantum hardware [13].
* 12-amino acid peptides: Pushed up to 12 amino acids using 33 trapped-ion qubits via digitized-counterdiabatic methods (BF-DCQO) [14].
Despite these demonstrations, current hardware limits remain severe. While the number of qubits required for coarse-grained folding models falls within current technological capabilities, the primary bottleneck is the extraordinarily high number of interaction terms in the Hamiltonian, which results in a massive quantum gate count that exceeds what today's noisy hardware can reliably execute [15]. Hardware constraints such as limited qubit connectivity, decoherence, gate fidelities, and crosstalk during overpacked circuit execution continue to restrict performance [16][17].
Projected Milestones
Projected milestones center on transitioning from simplified, coarse-grained peptide benchmarks to larger, biologically significant proteins that require advanced simulation techniques, warm-starting strategies, and fault-tolerant hardware [18]. Meeting these milestones will require continuous improvements in physical qubit fidelities, error mitigation techniques, and software abstraction layers that make hybrid algorithms more scalable for domain experts [19].
Would you also like to know how warm-starting techniques improve quantum protein folding performance?Réponse terminée. Une option de suivi est disponible.
Examinons les alternatives :
- Modifier la requête.
- Démarrer une nouvelle conversation.
- Supprimer des sources (si elles ont été ajoutées manuellement).